Credential Exfiltration via Prompt Injection
Hidden instructions in webpages can trick AI agents into stealing their API keys.
Credential exfiltration through prompt injection is a structural weakness in how AI agents are built, one that lets a hidden instruction buried in a webpage, an email, or a support ticket quietly pull API keys and OAuth tokens out of a system and... It's a structural weakness in how AI agents are built, one that lets a hidden instruction buried in a webpage, an email, or a support ticket quietly pull API keys and OAuth tokens out of a system and hand them to an attacker. Understanding why this works, link by link, is the only way to figure out where to break the chain.
How indirect prompt injection works: the mechanism that turns retrieved content into instructions
A large language model reads everything in one context window. There's no wall in the architecture that separates a developer's trusted instructions from a stranger's text pulled in from a webpage. Every token looks the same to the model, whether it came from a system prompt written by an engineer or a comment field filled out by an attacker.
That is a direct consequence of how transformers work. It's a direct consequence of how transformers work. The same design that lets a model handle open-ended language, translate between tongues, summarize a contract, answer a question about a photo, is the design that makes it impossible to architecturally guarantee an instruction came from someone trustworthy. The von Neumann architecture gave CPUs the ability to run any program by storing instructions and data in the same memory, and that exact choice is what made the buffer overflow a permanent category of bug. Transformers made the same trade. Instructions and data share a context window, and that sharing is the price of general-purpose language understanding.
Chatbots absorb this risk in a contained way, mostly. Agents don't. An agent reads email, browses the web, queries a database, summarizes a document, calls out to a third-party API, all as part of its normal job. It also tends to hold the credentials it needs to do that job (API keys, OAuth tokens, database passwords, SSH identities) in the same context window where it's dumping whatever it just scraped off the internet. And it can act. It can send an email, run a script, hit an API, post to Slack, all under the authority of whatever account it's running as. A chatbot that gets tricked says something wrong. An agent that gets tricked does something wrong, using someone else's credentials to do it.
There are three ways malicious instructions get into that context window, and they don't carry equal risk. Direct injection is when the attacker is also the user: someone types a jailbreak prompt straight into the chat box. The blast radius is small, since the person doing the attacking is mostly just attacking their own session.
Indirect prompt injection is different in kind, not degree. The malicious instruction sits inside content the agent reads on someone else's behalf, a webpage, a PDF, an email, a Slack message, a calendar invite, a pull request comment, an API response, a customer support ticket. The person harmed never sees the payload. They just asked their assistant to summarize an inbox, and the assistant did something else instead. Stored prompt injection is a slower variant of the same idea: the payload is in a knowledge base, a RAG index, or long-term memory, waiting for the agent to ingest it during ordinary operation, days or weeks after it was planted.
Research has split the practical outcomes of these injections into two buckets: goal hijacking, where the model is steered into doing a task the attacker chose, and prompt leaking, where the model is coaxed into revealing instructions or data it was supposed to keep hidden. Credential exfiltration usually rides in through the second bucket, dressed as the first.
None of this can be fixed the way SQL injection got fixed. SQL injection was tamed because SQL has a fixed, checkable grammar that allows inputs to be validated and sanitized before they are parsed as instructions. Natural language has no such grammar. The space of phrasings that can carry an adversarial instruction is close to unbounded, and every attempt to filter inputs more aggressively tends to flag more legitimate text along with it. There's no clean boundary to draw.
The credential exfiltration chain: how a hidden instruction harvests and transmits secrets
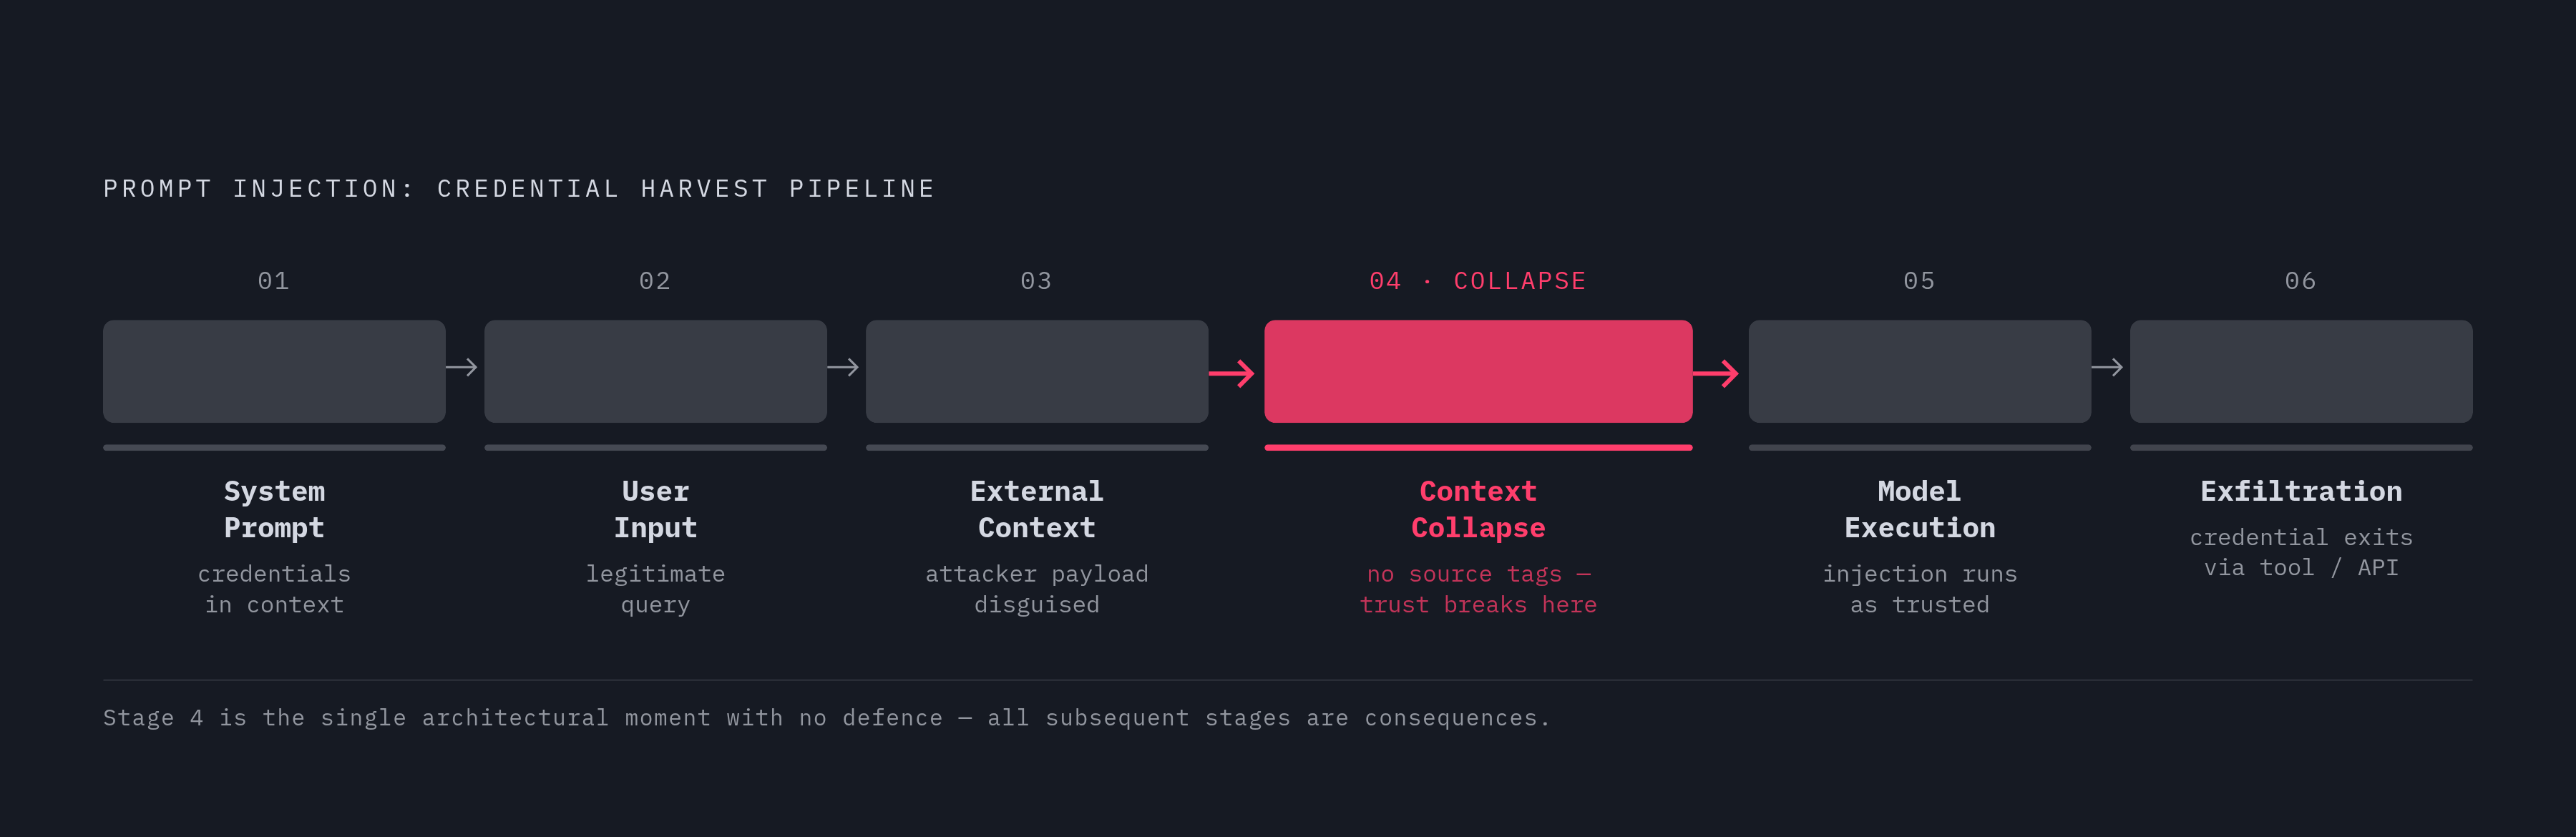
Production agents routinely park sensitive credentials, API keys, database passwords, OAuth tokens, SSH identities, in the same context window where they process content nobody vetted. That's the setup. Indirect prompt injection is the trigger.
Trace it as a pipeline, because the trust breaks down at a specific point, not everywhere at once. The first stage is the system prompt: a developer's instructions, often with credentials sitting nearby or injected directly into that context. Stage two is the user's input, a normal, legitimate query. Stage three is external context: whatever the RAG system pulled back, a webpage, an email body, a tool's response. This is where the attacker's payload actually arrives, dressed up as ordinary retrieved content. Stage four is the point of no return: all three streams, system prompt, user input, external context, collapse into one undifferentiated stream of tokens. There is no tag on any token that says where it came from.
Stage five is the model acting on the injected instruction as though it had every right to. The output isn't a refusal or a red flag, it's a response that quietly contains the credential material the attacker wanted. The final stage is the credential leaving the building, through a tool call, an outbound API request, an image fetch, or a message sent somewhere the attacker controls.
The economics favor the attacker badly. One payload that works is enough. Defenders, meanwhile, have to secure every single surface the agent touches, every email, every document, every webpage, every internal wiki page, every other agent's output that might get fed back in. That's an asymmetry, not a fair fight.
Even when a defender puts a filter on the model's output, checking for anything that looks like a credential, the payload can dodge it. Encode the exfiltrated secret in Base64, swap characters for Unicode look-alikes, paraphrase it into something that reads as an innocuous sentence. The output looks clean to a filter built to catch obvious strings, and the secret still gets out.
How prevalent this attack surface is: what large-scale web scans found
A large-scale scan (arXiv 2604.27202) gives a sense of how far this has already spread across the open web, not in a lab, but in production. Researchers scanned 1.2 billion URLs across 24.8 million hosts and found 15,300 validated instances of indirect prompt injection spread across 11,700 pages.
The detail that matters most isn't the total count, it's who those injections were built for. Of the 15,300 instances, 13,400, or 87%, were invisible to a human looking at the page. These weren't attempts to trick a person reading the site. They were built for an agent that would fetch the page's raw content and never render it visually.
The concealment techniques cluster into a handful of recurring tricks. Color and contrast manipulation, text set the same color as its background, accounted for 2,397 cases. Occlusion, hiding text behind other elements, appeared in 1,860 cases. Viewport-based hiding, pushing content off-screen where no human would scroll, appeared in 1,802 cases. Across HTML-embedded injections generally, only about 5.1% were visible to a person, while 58.6% relied on some form of rendering-based concealment. The web is already seeded with payloads meant for machines, sitting quietly in pages that look completely normal to anyone glancing at them.
EchoLeak, CamoLeak, and ForcedLeak: three production exploits that ran the full exfiltration chain
None of this stayed theoretical. Three separate exploits, against three separate enterprise platforms, each carried a CVSS score above 9.0, and each demonstrated the injection-to-exfiltration chain in a real, shipped product.
EchoLeak (CVE-2025-32711, CVSS 9.3) hit Microsoft 365 Copilot. Aim Security's research team, Aim Labs, found it and reported it to Microsoft, which patched it in its June 2025 Patch Tuesday release. It's been described as the first zero-click exploit against an AI agent: the attacker sends a crafted email, the victim never opens it, Copilot reads it anyway during routine background processing, and a completely unrelated later query is what actually triggers the leak. Aim Labs framed the underlying flaw as an "LLM Scope Violation," where untrusted external input manipulates the model into reaching into data well outside what that input should ever touch, chat logs, OneDrive files, SharePoint content, Teams messages, whatever the organization had preloaded. The exploit got past several defenses in one pass: it slipped by Microsoft's XPIA prompt-injection filters, sidestepped Copilot's link redaction, and abused a Microsoft domain that was already approved under Content Security Policy to move data out automatically. The payload itself was concealed in a way that made it invisible to a person viewing the content, yet fully legible to the model parsing it. Microsoft found no evidence of exploitation in the wild and patched it server-side. It stands as the first documented case of prompt injection being weaponized for actual data exfiltration in a production AI system, and that "first" matters for understanding how fast this category moved from research paper to real incident.
CamoLeak (CVE-2025-59145, CVSS 9.6) targeted GitHub Copilot Chat. The payload sat inside a pull request description, hidden with invisible HTML or Markdown comment syntax. A victim would open the PR for review, an entirely routine action, and Copilot would execute the buried instruction on their behalf without any unusual signal in the UI. The target was source code, API keys, and secrets inside private repositories, and the victim's own machine was not directly compromised in the conventional sense. The exfiltration method was the clever part: a CSP bypass that used GitHub's own Camo image proxy, so attacker-controlled but policy-compliant image URLs carried encoded data straight out of the victim's browser, through infrastructure GitHub itself runs and vouches for. It was disclosed responsibly through HackerOne in June 2025, and GitHub's mitigation, disabling image rendering in Copilot Chat, landed on August 14, 2025. The channel carrying stolen data out was a domain everyone already trusted, which made the outbound traffic indistinguishable from normal agent behavior.
ForcedLeak (CVSS 9.4) went after Salesforce Agentforce. Noma Security's research team, Noma Labs, found and reported it on July 28, 2025, with disclosure following in September 2025. Any organization running Agentforce with Web-to-Lead enabled was exposed. An indirect prompt injection could leak sensitive CRM data by way of a public-facing Web-to-Lead form, the entry point in this case. What stands out is the cost of entry: the attacker got in by way of a $5 expired domain purchase. That gap, a negligible acquisition cost against an organization's entire CRM dataset, is the whole story in miniature.
How far the attack has evolved: from single-step exploits to multi-stage promptware
Credential theft doesn't have to be the finish line. It can just as easily be one stage inside a longer campaign, something closer to a kill chain than a single trick, and framing it that way changes how defenders ought to think about it.
The first stage is initial access: the prompt injection itself, the foothold. Stage two is privilege escalation, jailbreaking whatever safety alignment the model was given so it'll follow instructions it was trained to refuse. Stage three is reconnaissance, pulling out the system prompt, mapping what tools and data the agent can reach, figuring out what's worth stealing before stealing it.
Read this way, credential exfiltration stops looking like an isolated exploit and starts looking like a mechanism that persists across a campaign, resurfacing at each stage where the agent's access can be widened or its secrets can be pulled out. EchoLeak, CamoLeak, and ForcedLeak each showed the exfiltration half of that chain running to completion inside a real product. The reconnaissance and escalation stages that can precede it are the part still being mapped out, and defending against a kill chain built this way takes more than a filter on the model's output. It takes rethinking what an agent is allowed to hold in its context window from the start.
Sources
- Caught in the Act(ivation): Toward Pre-Output and Multi-Turn Detection of Credential Exfiltration by LLM Agents
- The Promptware Kill Chain: How Prompt Injections Gradually Evolved Into a Multistep Malware Delivery Mechanism
- EchoLeak: The First Real-World Zero-Click Prompt Injection Exploit in a Production LLM System
- The Framing Gap: Indirect Prompt-Injection Exfiltration Defeats Surface-Level Defenses in Tool-Using Agents
- Indirect Prompt Injection in the Wild: An Empirical Study of Prevalence, Techniques, and Objectives